Tool Gate · How it works
How the Agent Reliability Harness gate works
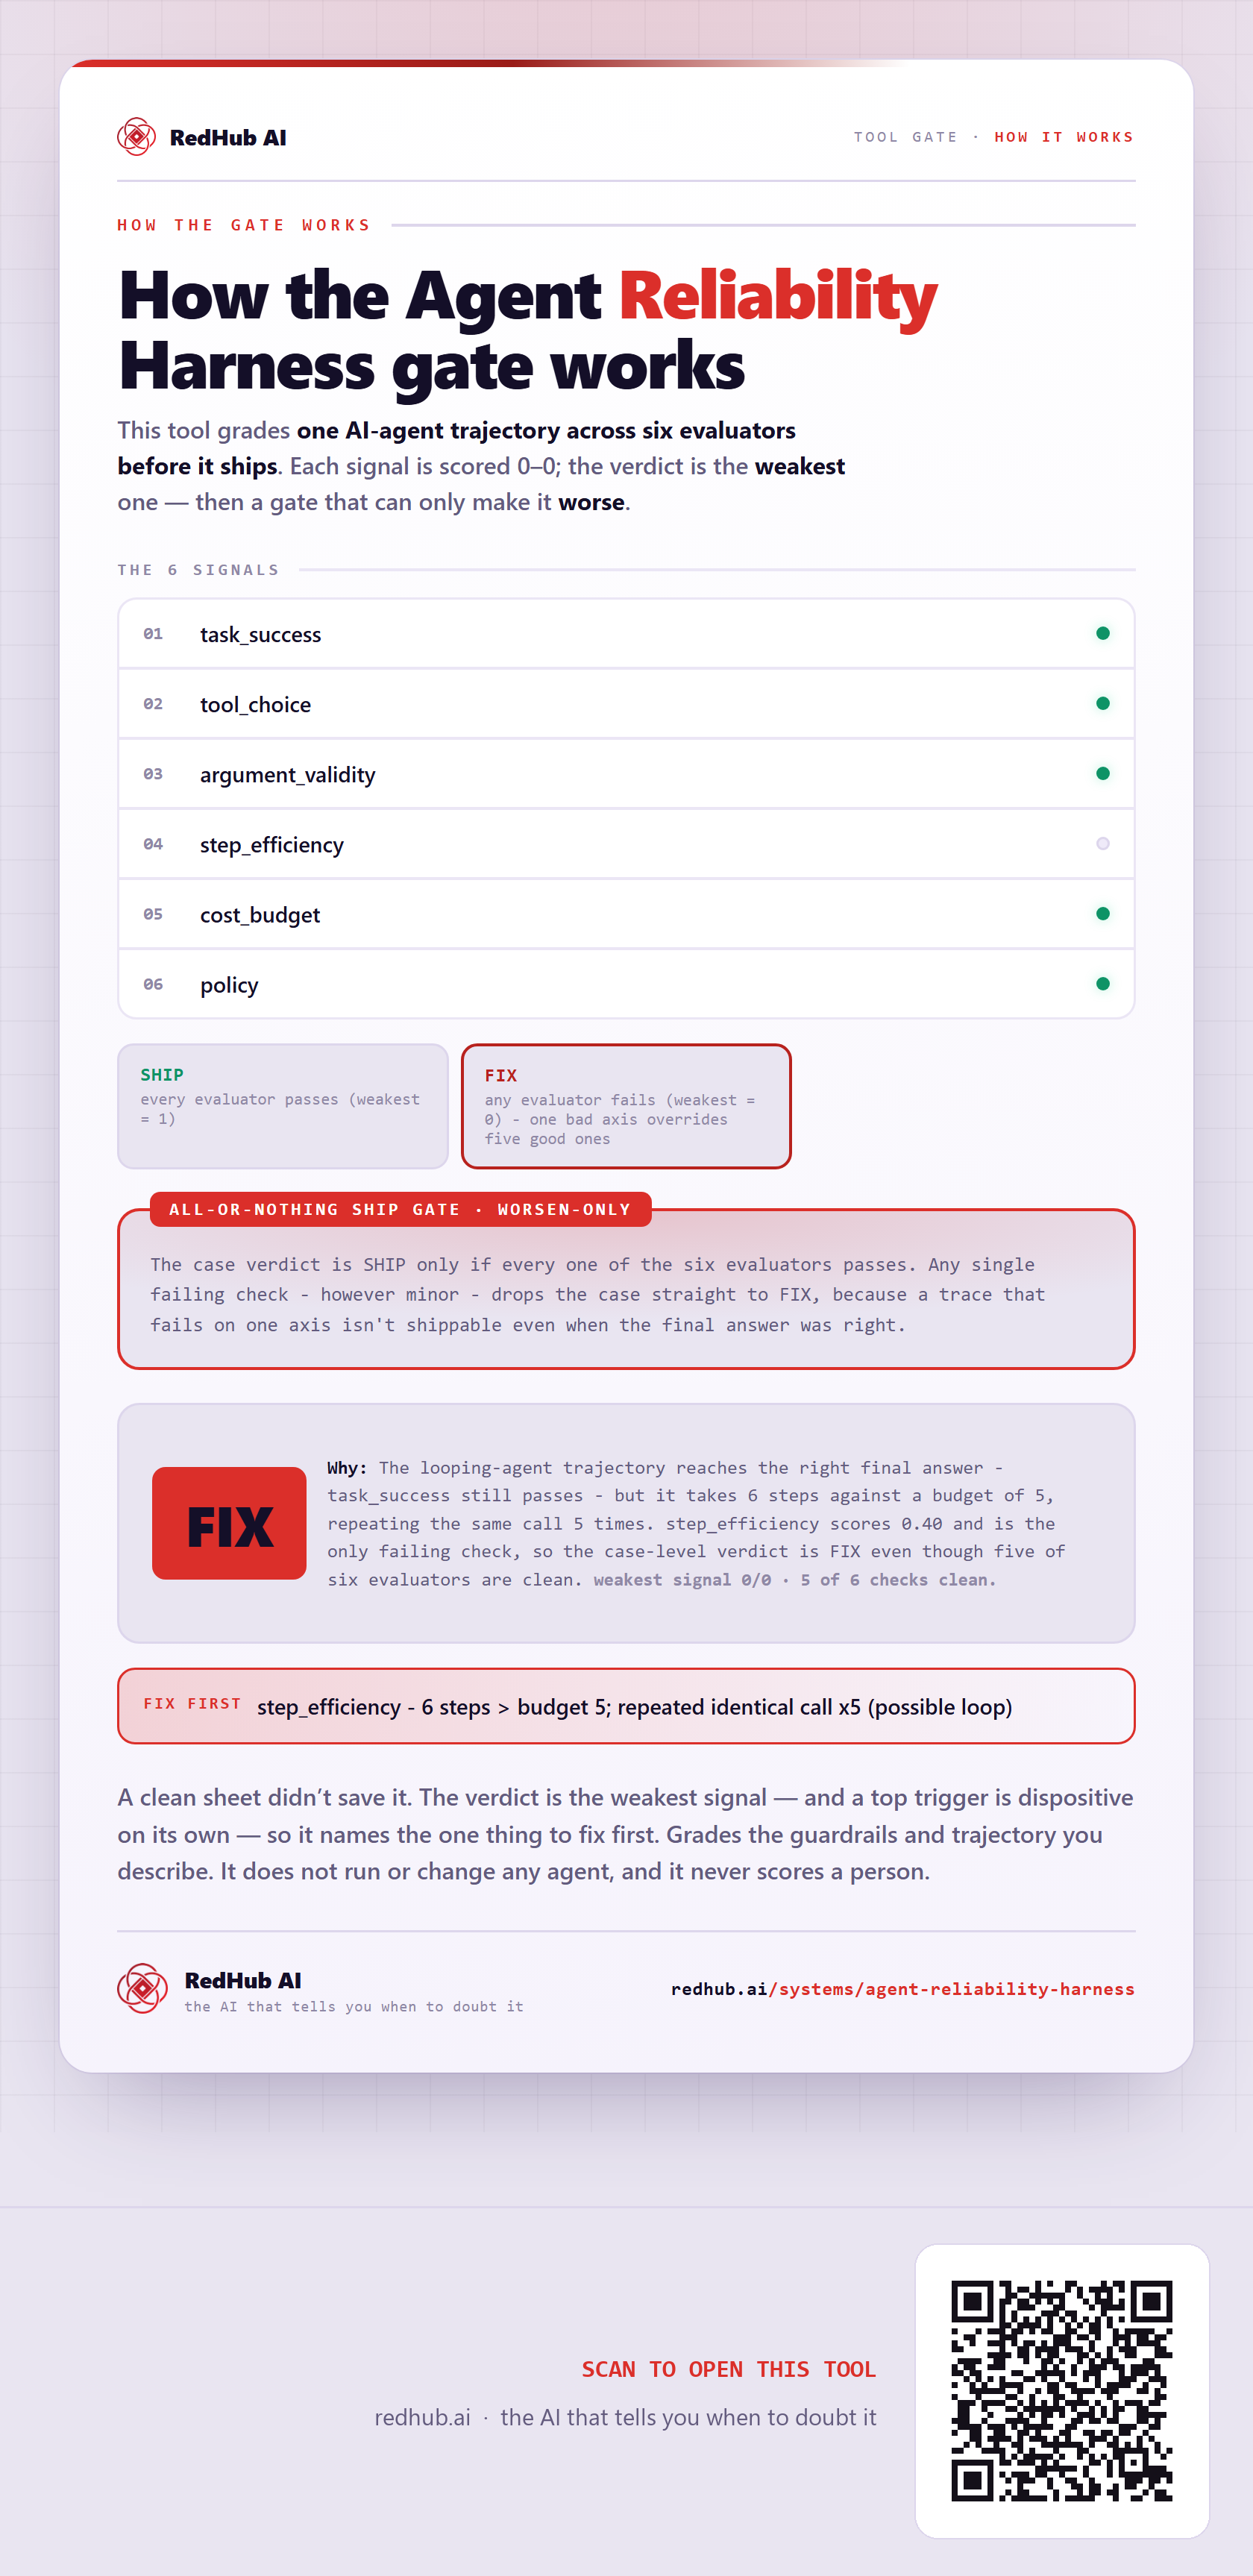
How the Agent Reliability Harness scores one agent trajectory across 6 evaluators — task success, tool choice, argument validity, step efficiency, cost, policy — and ships only if every one passes: the default looping agent reaches the right answer but repeats a call, so step efficiency alone drops it to FIX with the other five clean. Run as a one-case suite, one failing evaluator is a 0% pass rate and reads FIX; a suite of several cases reads HOLD when it is short of SHIP and 80% or more pass.
How the gate works
This tool grades one AI-agent trajectory, run as a one-case suite, across six evaluators before it ships. Each of 6 signals is scored 0–1 from your own evidence; the verdict is the weakest one. The verdict gate then reads the suite: SHIP needs every case passing and a reliability score of 0.90 or more, HOLD needs 80% or more of the cases passing, and anything less reads FIX. One trajectory is a one-case suite, so one failing check reads FIX.
The 6 signals
| Signal | Role |
|---|---|
| task_success | signal |
| tool_choice | signal |
| argument_validity | signal |
| step_efficiency | signal |
| cost_budget | signal |
| policy | signal |
The verdict bands
A case passes only when every graded evaluator passes. The suite reads SHIP only when every case passes and its reliability score is 0.90 or more; short of that it reads HOLD while 80% or more of its cases pass, and FIX below 80%. One trajectory is a one-case suite, so a single failing check is a 0% pass rate and reads FIX, whatever its reliability score.
In the worked sample 5 of 6 checks pass, reliability 0.90 (weakest 0) and it still reads FIX — The looping-agent trajectory reaches the right final answer - task_success still passes - but it takes 6 steps against a budget of 5, repeating the same call 5 times. step_efficiency scores 0.40 and is the only failing check, so the case fails. Run as a one-case suite, that is a 0% pass rate and a FIX verdict at a reliability score of 0.90, even though five of six evaluators pass. Marked fix first on this sample: step_efficiency - 6 steps > budget 5; repeated identical call x5 (possible loop).
Common questions
Can an agent reach the right answer and still read FIX on the Agent Reliability Harness?
Yes. A case passes only when every graded evaluator passes, and the verdict reads the suite's pass rate before its reliability score. In the worked sample the looping agent's final answer is right, so task_success passes, but step_efficiency fails on 6 steps against a budget of 5. Run as a one-case suite, that is a 0% pass rate and a FIX verdict at a reliability score of 0.90.
When does the Agent Reliability Harness read HOLD?
HOLD is the middle verdict of a suite. It is short of SHIP, which needs every case passing and a reliability score of 0.90 or more, while 80% or more of its cases pass. Below 80% the suite reads FIX. The command-line runner exits non-zero on FIX, and not on HOLD.
Grades the guardrails and trajectory you describe. It does not run or change any agent, and it never scores a person.
Embed this diagram
Free to share and embed with attribution (CC BY 4.0) — keep the link to redhub.ai.
Interactive — renders the live diagram
<iframe src="https://redhub.ai/visuals/tool/agent-reliability-harness.html" title="How the Agent Reliability Harness gate works — RedHub AI" width="760" height="1672" loading="lazy" style="border:0;width:100%;max-width:760px"></iframe>
<p style="font:14px/1.5 system-ui,sans-serif"><a href="https://redhub.ai/visuals/tool/agent-reliability-harness">How the Agent Reliability Harness gate works</a> — by <a href="https://redhub.ai">RedHub AI</a>, the AI that tells you when to doubt it.</p>
Image + link — a static picture for any blog
<a href="https://redhub.ai/visuals/tool/agent-reliability-harness"><img src="https://redhub.ai/visuals/tool/agent-reliability-harness-share.png" alt="Diagram of the Agent Reliability Harness: six pass/fail evaluators, three verdict bands (SHIP, HOLD and FIX), and a FIX verdict driven by the single failing step-efficiency check on a looping agent whose final answer was correct." width="760" loading="lazy" style="max-width:100%;height:auto;border-radius:16px"></a>
<p style="font:14px/1.5 system-ui,sans-serif"><a href="https://redhub.ai">RedHub AI</a> — the AI that tells you when to doubt it.</p>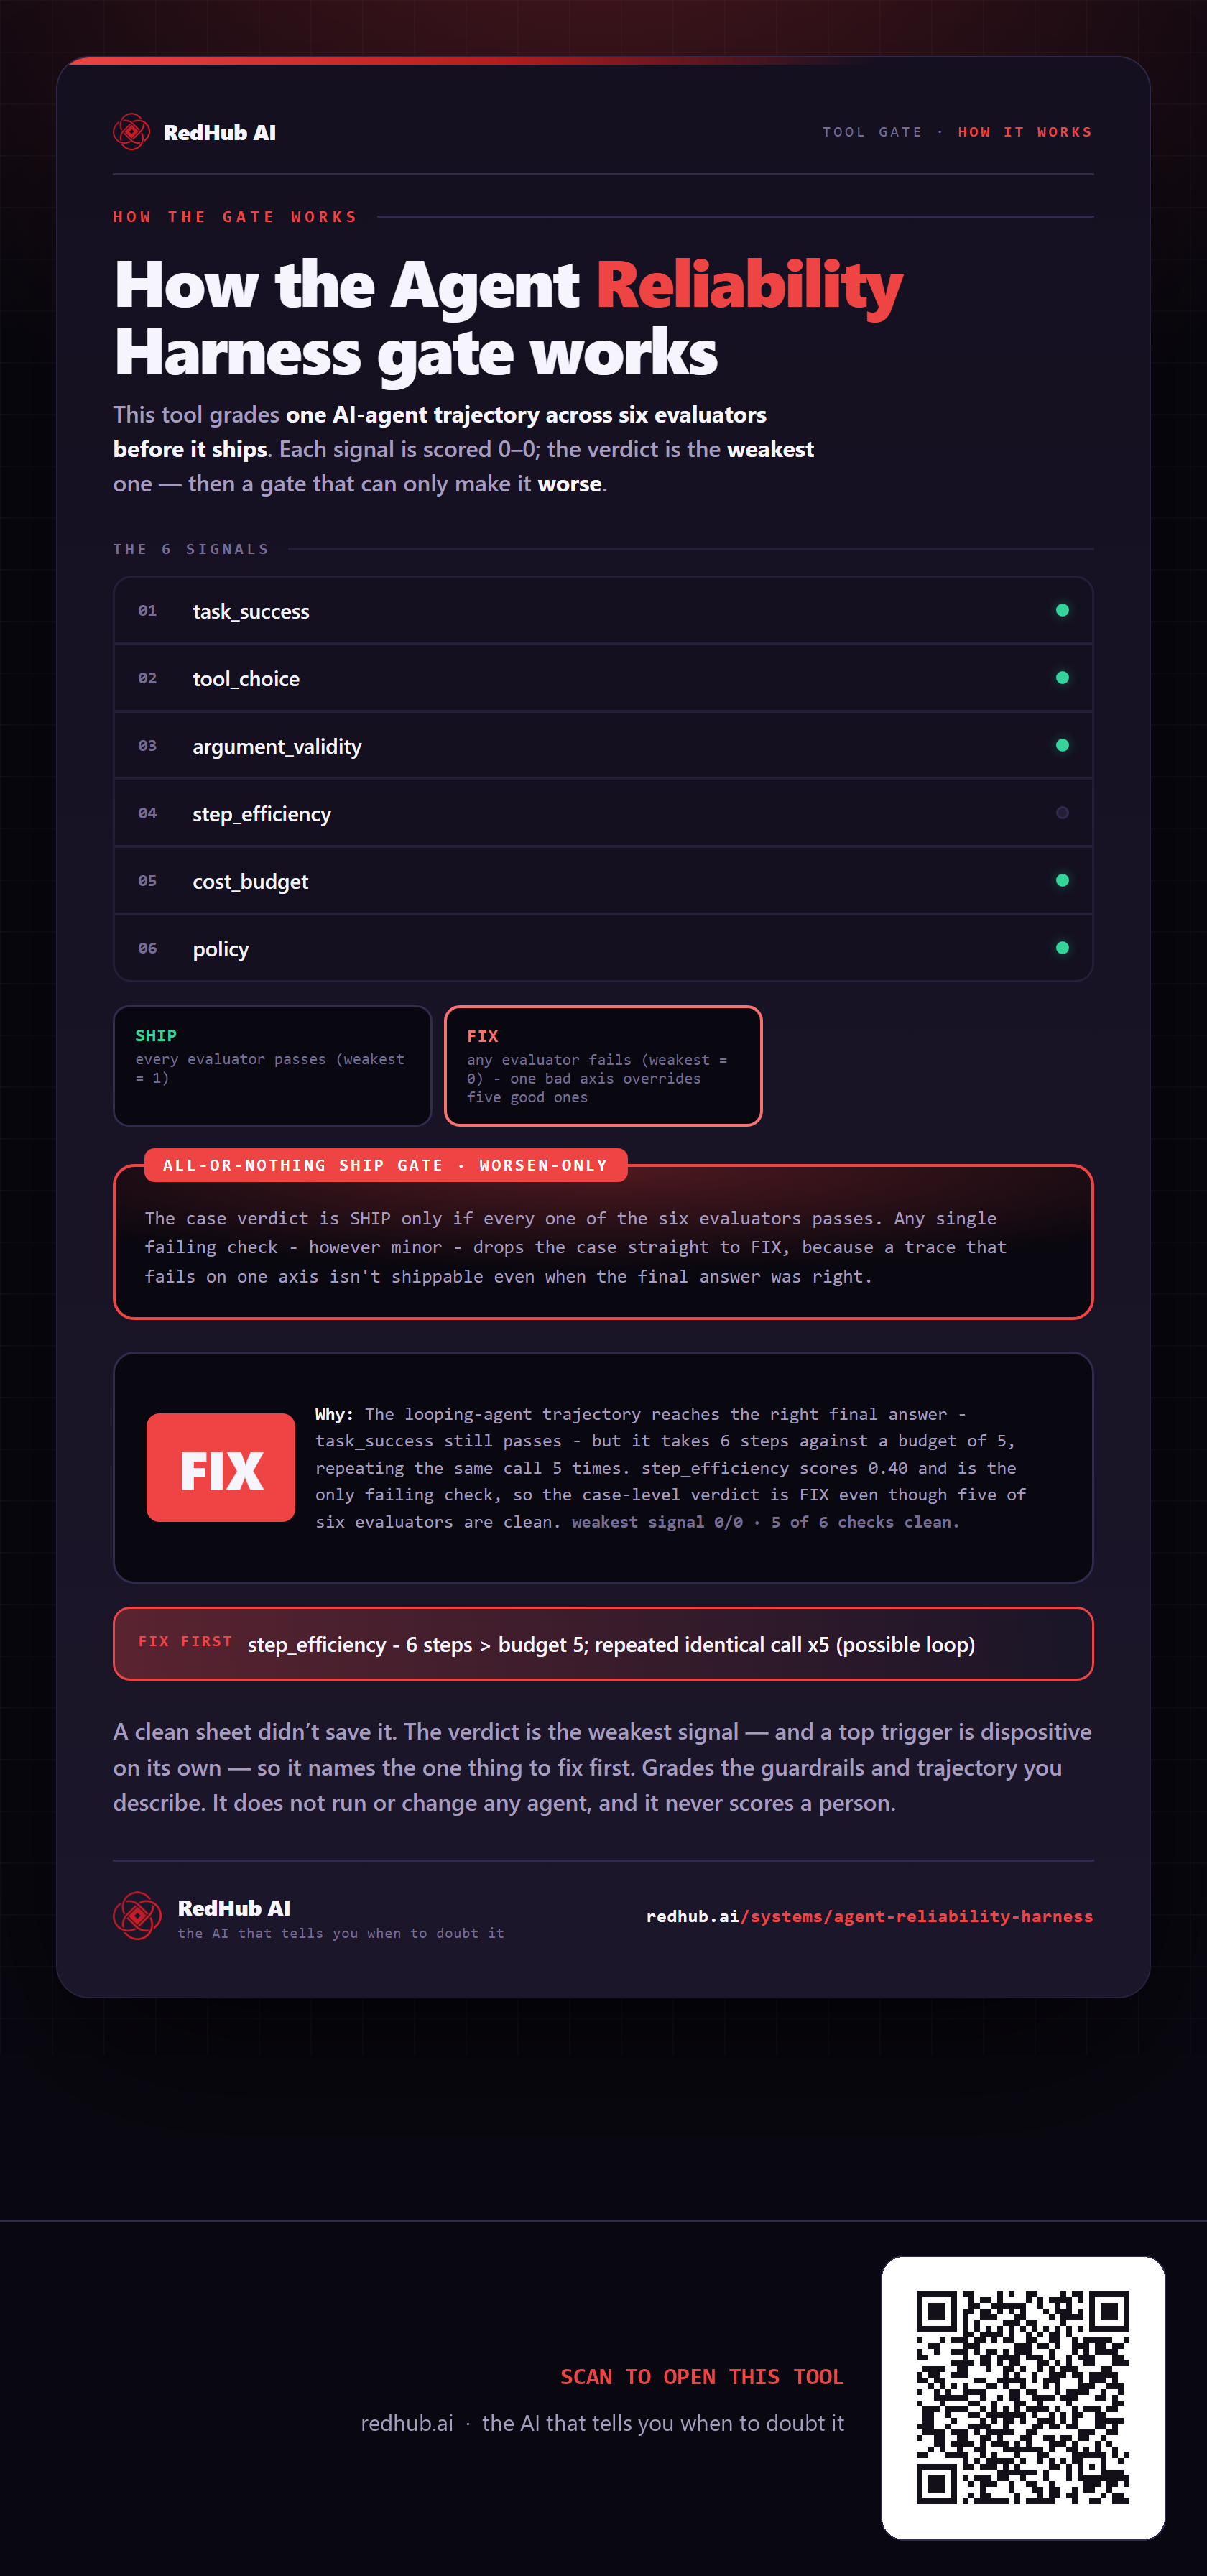
This is how Agent Reliability Harness works. More diagrams in the Visual Field Guide.