Are your documentsworth grounding on?
A retriever can find the right document and still return the wrong answer — because the document is stale, contradicted, or off-limits. This gate grades the corpus before you point AI at it.
Garbage in, confident answer out.
Mark six controls. Get one verdict.
Mark the corpus
A grounding control is below full, so this is UNGROUNDED even if its weakest control would only read STALE — contradictory authoritative docs make retrieval a coin flip, and unmapped permissions make it a leak.
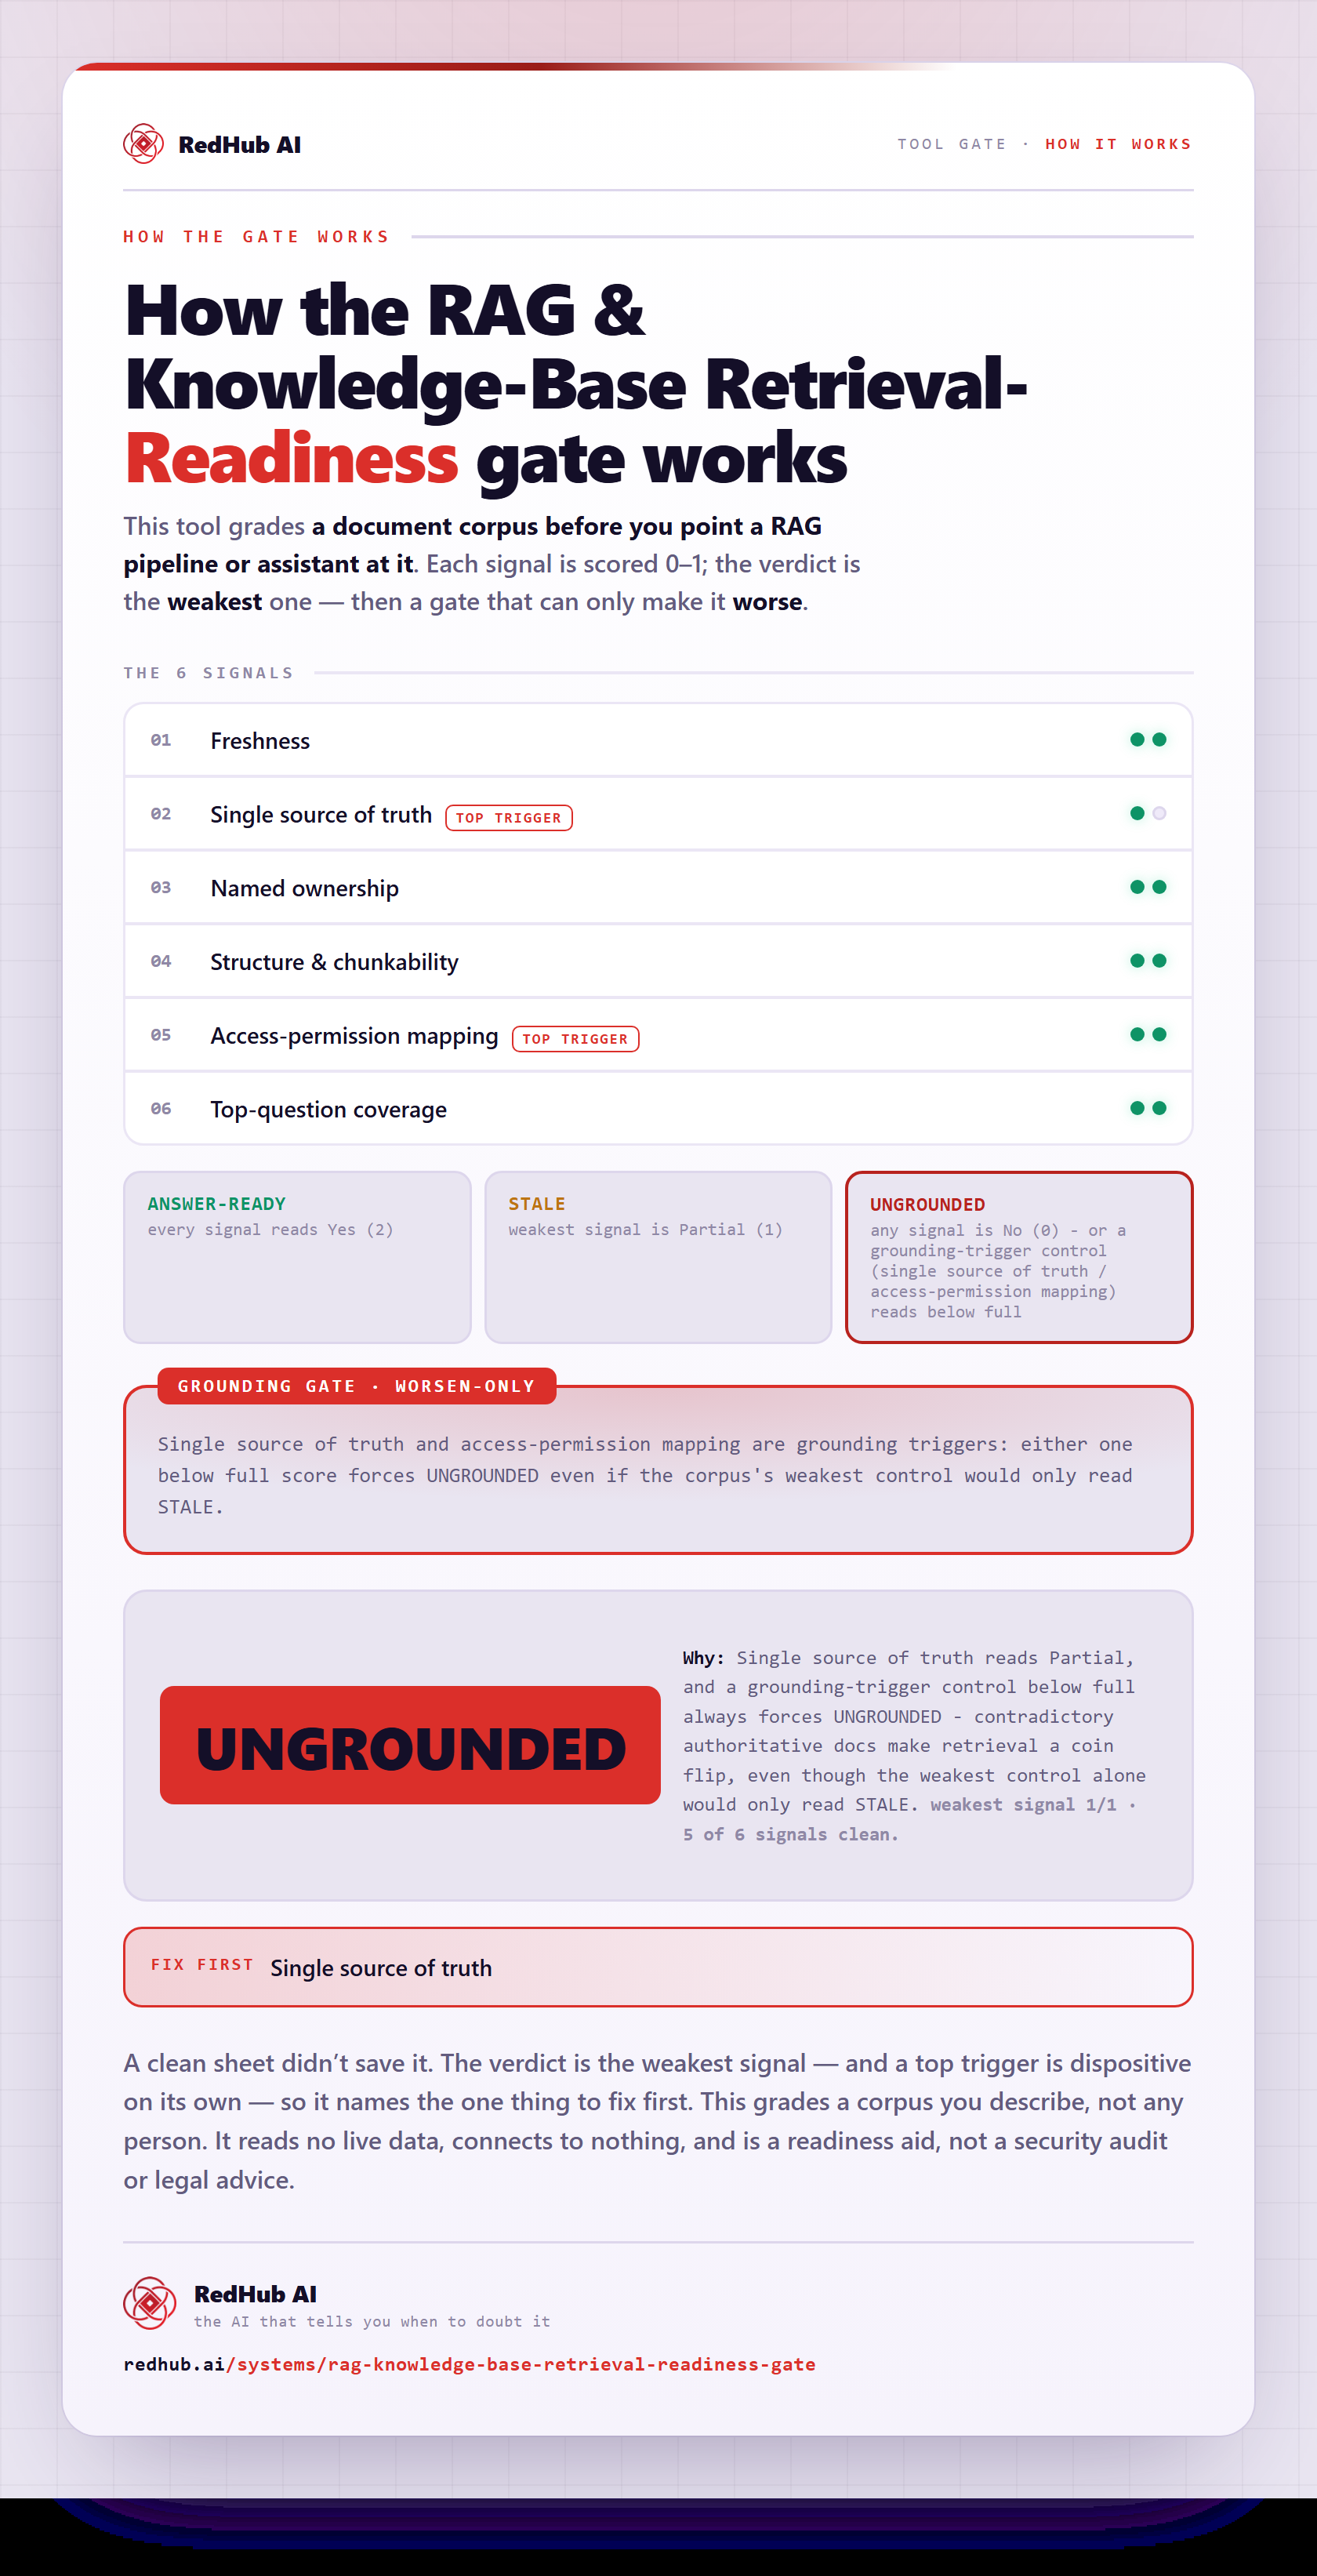
How the gate works, in one image
How the RAG & Knowledge-Base Retrieval-Readiness Gate grades six corpus signals by the weakest and forces UNGROUNDED when the single source of truth is missing — the same math the demo runs, as a diagram you can share or embed anywhere.
View & embed the full diagramA runnable engine, verdict-for-verdict.
The workbook reproduces this engine exactly. Notice HR policies and Finance procedures: both score 92%, both read UNGROUNDED — one for a contradiction, one for unmapped permissions. The gate is what makes a high score honest.
--------------------------------------------------------------------------
RAG & KNOWLEDGE-BASE RETRIEVAL-READINESS GATE
Is this corpus fit to ground an AI's answers?
--------------------------------------------------------------------------
CORPUS                     WEAK   MEAN  VERDICT      GATE
--------------------------------------------------------------------------
Product docs                  2   100%  ANSWER-READY
Support KB                    1    83%  STALE
HR policies                   1    92%  UNGROUNDED   FIRED
Sales playbook                1    75%  STALE
Legacy wiki                   0    42%  UNGROUNDED   FIRED
Finance procedures            1    92%  UNGROUNDED   FIRED
--------------------------------------------------------------------------
Batch: UNGROUNDED — DO NOT GROUND ON THIS
--------------------------------------------------------------------------
Support KB: fix first — Freshness
HR policies: fix first — Single source of truth
Sales playbook: fix first — Named ownership
Legacy wiki: fix first — Access-permission mapping
Finance procedures: fix first — Access-permission mapping
--------------------------------------------------------------------------
Verdict is the weakest control; the mean is context only. The gate
forces UNGROUNDED on a live contradiction or unmapped permissions.
Deterministic, offline; it scores the corpus, not people, and reads no
live data. Distinct from a retrieval-metric grader — this grades content.
--------------------------------------------------------------------------
Three rules it never breaks.
A content gate, not a retrieval benchmark.
- A content-readiness gate for a corpus you are about to ground AI on.
- A weakest-control verdict with a dispositive grounding gate.
- Deterministic and offline — you mark the controls, it scores.
- A retrieval-metric grader — use the RAG Retrieval Grader for Recall@k.
- A poisoning probe — use the Context-Poisoning Probe for that.
- A live scan — it reads no documents.
Scope. This grades a corpus described in the answers, not any person. It does not retrieve or inspect the corpus. It is a readiness aid, not a security audit or legal advice.
For anyone grounding AI on their own documents.
- Ops and founders whose assistant “answers from stale docs.”
- Teams standing up a support bot or internal Q&A on a knowledge base.
- Anyone deciding whether a corpus is ready before wiring up RAG.
- Measuring retrieval quality — use the RAG Retrieval Grader.
- Scoring people — it grades the corpus, not anyone.
- A live security scan — it reads nothing.
Where it sits in the stack.
Answers before you buy.
Grade the corpus first.
Then ground on it.
One purchase, lifetime access, 12 months of updates. $89, once.
Scope. This grades a corpus described in the answers, not any person. It does not retrieve or inspect the corpus. It is a readiness aid, not a security audit or legal advice.
Sold by RedHub AI LLC · Secured by Stripe · redhub.ai